The Performance Advisor orders the Indexes that it suggests by their respective Impact. Impact indicates the estimated performance improvement that the suggested index would bring.
Performance Advisor如何对索引提出建议和排名
The Performance Advisor monitors queries that take longer than 100 milliseconds to execute and groups these queries into common query shapes. The Performance Advisor calculates the inefficiency of each query shape by considering the following aggregated metrics from queries which match the shape:
执行查询所花费的时间。
扫描的文档数量。
返回的文档数量。
平均对象大小。
为了建立推荐索引,Performance Advisor会在公式中使用这些指标来计算Impact ,即创建与查询结构匹配的索引所带来的性能改进。 当Performance Advisor建议索引时,它会按索引的Impact对索引进行排名。 Impact由读取的浪费字节总数决定。
索引字段顺序
查询结构中的查询操作类型会影响用于构造索引的顺序。 下表显示了Performance Advisor如何按相对重要性顺序对各种操作类型进行排名:
限制建议的索引
Performance Advisor不会建议具有超过 16 个字段的索引。
此外,仅当受影响查询的扫描文档与返回文档之间的差异大于 500 时, Performance Advisor才会建议使用索引。
索引去重
Performance Advisor会在提出建议之前对重叠索引进行去重。 例如,考虑Performance Advisor是否计算以下潜在的建议索引:
{ a : 1 } { a : 1, b : 1 }
由于 { a : 1 } 是 { a : 1, b : 1 } 的前缀,因此Performance Advisor仅建议使用 { a : 1, b : 1 }。 要了解有关索引前缀的更多信息,请参阅前缀。
示例:纽约市出租车数据
此示例使用名为cab-db的数据库,其中包含有关纽约市出租车行程的信息,其中包含上下车时间、行程距离和行程费用明细字段。 集合yellow中的典型文档如下例所示:
{ "_id" : ObjectId("5db9daab0b2a17b7706cd6a3"), "pickup_datetime" : "2014-06-30 02:09:23", "dropoff_datetime" : "2014-06-30 02:20:36", "passenger_count" : 2, "trip_distance" : 3, "fare_amount" : 12, "tip_amount" : 2.6, "total_amount" : 15.6 }
该集合包含超过10万份文档,因此需要根据特定字段数据运行查询的应用程序将生成一些效率非常低的操作,除非您对该集合进行正确索引。
此应用程序的典型查询Atlas Search包含特定还车时间以及一个或多个其他字段的文档。 例如:
db.yellow.find({ "dropoff_datetime": "2014-06-19 21:45:00", "passenger_count": 1, "trip_distance": {"$gt": 3 } })
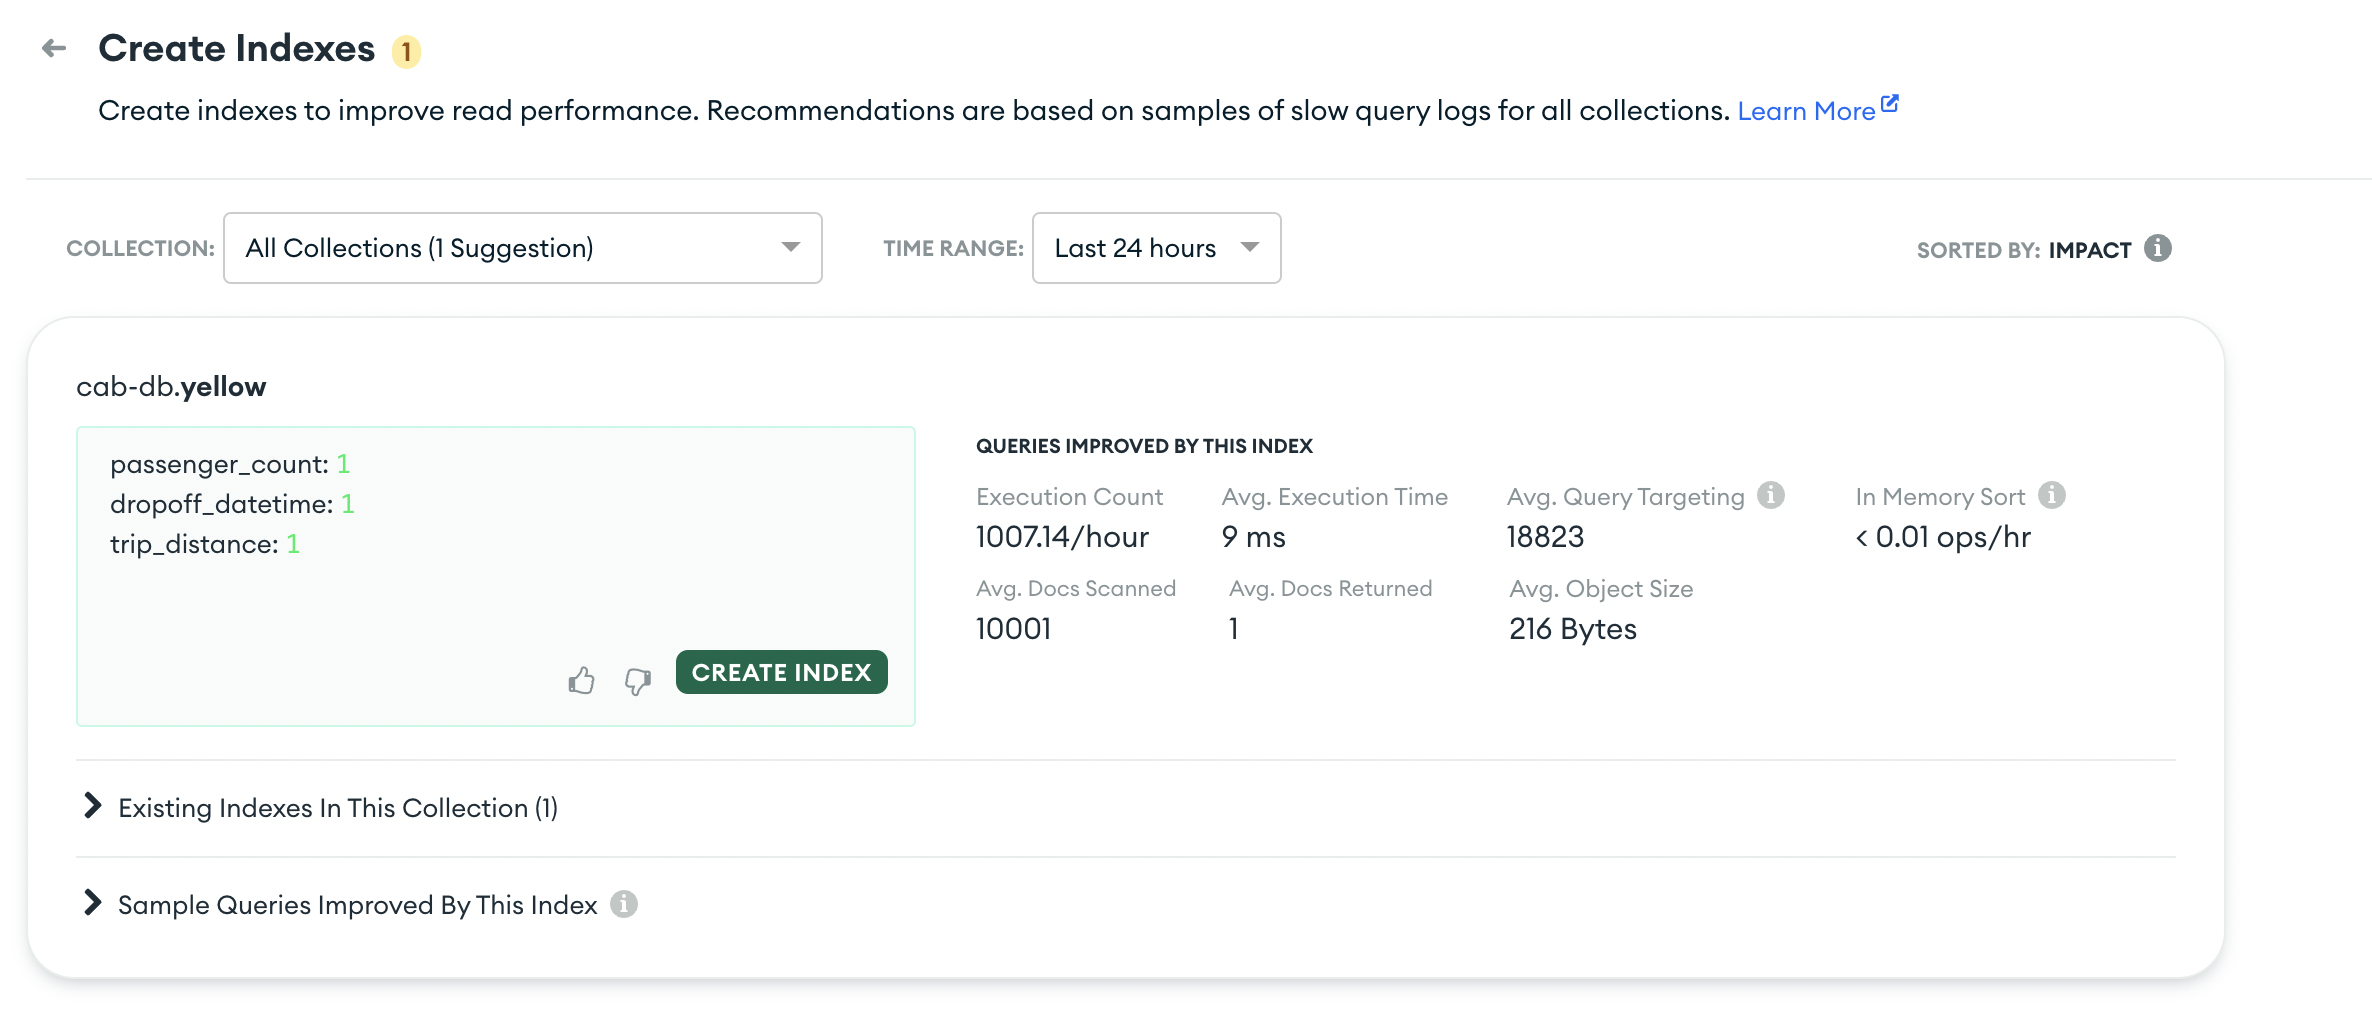
Performance Advisor建议使用以下索引来提高性能:
注意
默认情况下, Performance Advisor会显示集群中所有集合的索引建议。 要将推荐范围缩小到特定集合,请从Collection下拉菜单中选择一个集合。
Performance Advisor按对性能影响从大到小的顺序列出推荐的索引。
第一个建议是在三个字段上建立索引:
passenger_countdropoff_datetimetrip_distance
单击Create Index按钮,使用任何所需的附加选项创建索引。 要了解有关在Performance Advisor中创建索引的更多信息,请参阅创建建议的索引。
If you create this index, you remove the need for the database engine to scan the entire collection to find documents that match the query, which improves performance. Queries with the shape shown in the example return results in 50 milliseconds or less on the indexed collection, as opposed to several seconds on the unindexed collection.
注意
您还可以使用数据浏览器创建索引。