Sometimes the biggest performance gains come not from making core operations faster, but from eliminating unnecessary work surrounding them. That is exactly what we discovered while optimizing document lookup in MongoDB Atlas Search and Vector Search. By removing redundant query planning and execution overhead, we made search queries up to 5x faster without changing the underlying search algorithms.
When you run a $search or $vectorSearch query in MongoDB, two key stages work together to deliver the results. First, mongot, MongoDB's search process powered by Apache Lucene, executes the search query to identify and rank the most relevant documents. Then, mongod joins the search results with the corresponding BSON documents from the underlying collection using their _ids. The resulting documents can be further processed by additional aggregation pipeline stages before being returned to the application. Figure 1 illustrates this two-stage process:
Figure 1. Search execution in mongot and document materialization in mongod.
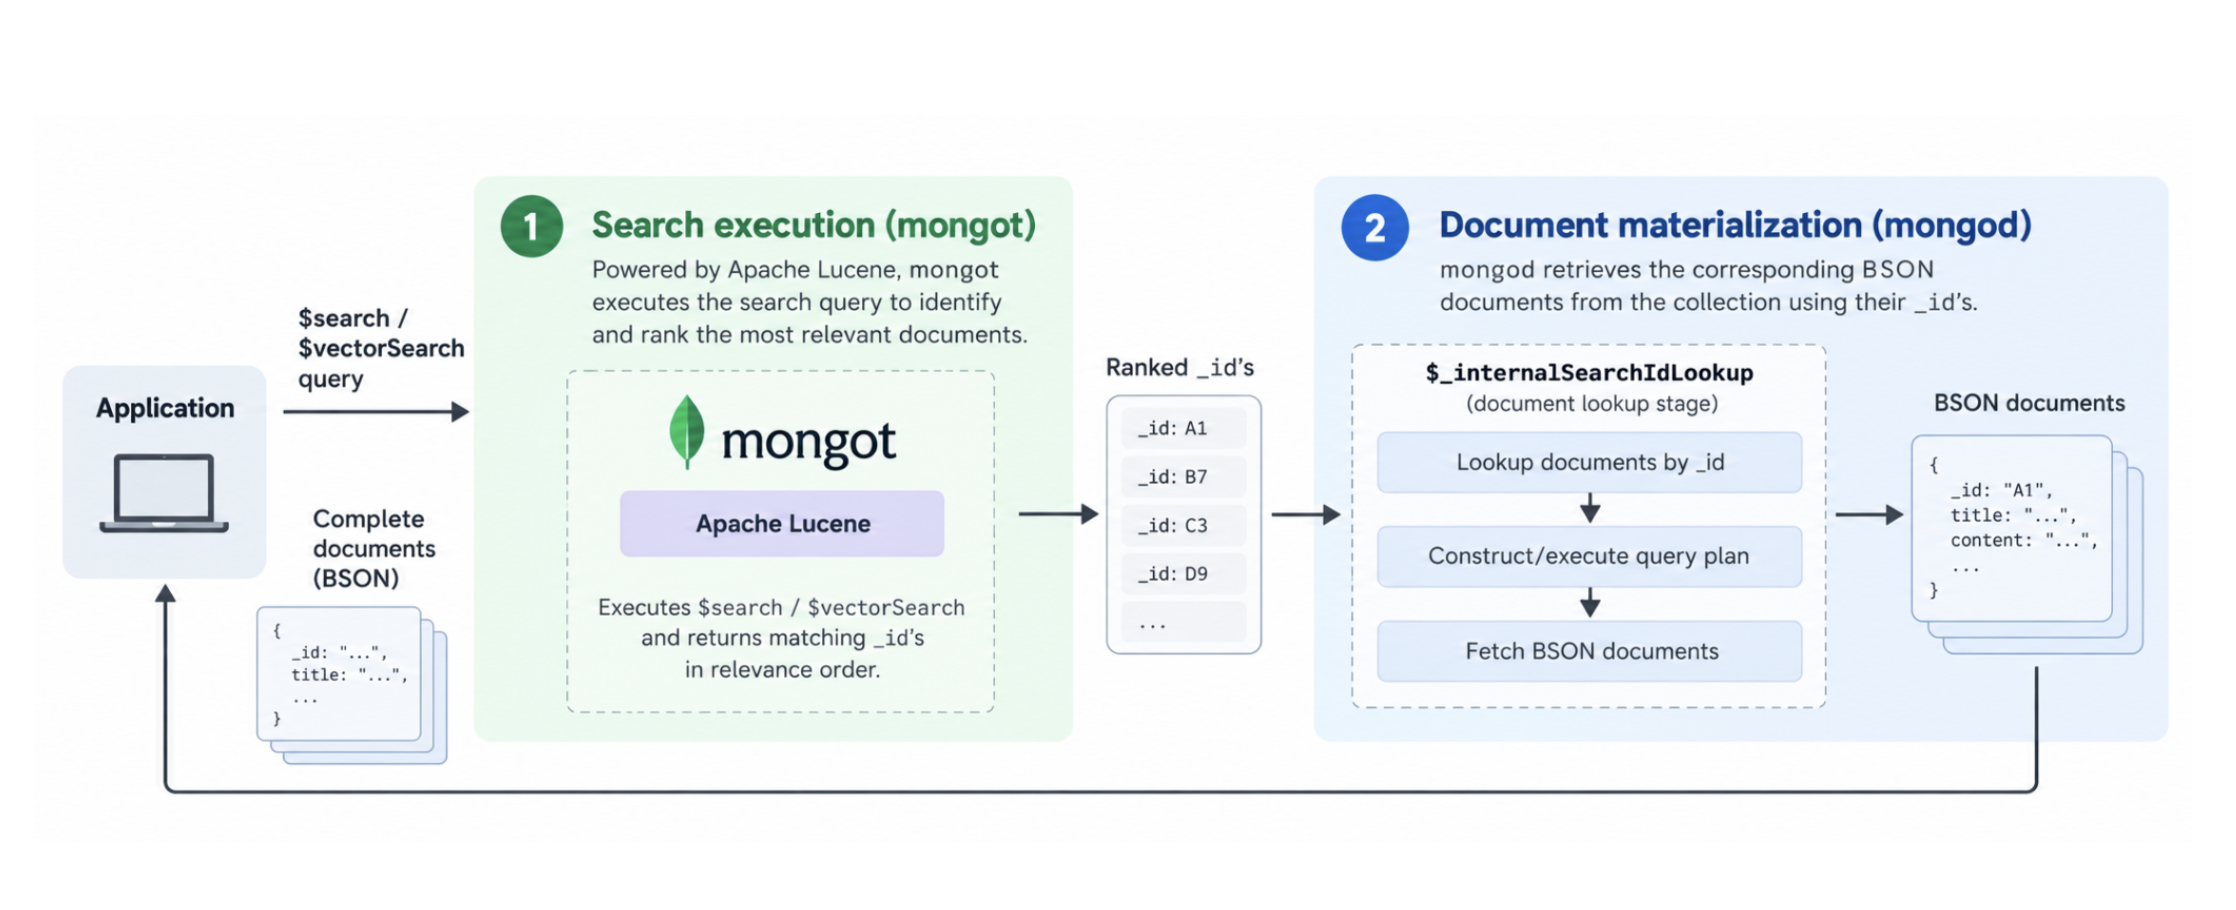
This second stage, known as document materialization, is handled by an internal aggregation stage called $_internalSearchIdLookup. While search execution has been extensively optimized, we discovered that document lookup had become a significant performance bottleneck. For every matching document, the stage repeatedly constructed a new query plan and acquired collection resources, introducing substantial overhead for queries returning hundreds or thousands of results. In our profiling, approximately 30% of mongod CPU time was spent on query planning and collection acquisition, rather than retrieving documents.
To address this, we redesigned the document lookup execution path to eliminate redundant query planning, reuse execution plans, and amortize resource acquisition across multiple lookups. The result: up to 4.9x faster $search queries, 5.5x faster $vectorSearch queries, and approximately 2.75x higher throughput under concurrency.
These optimizations shipped in MongoDB 9.0, are enabled by default, and require no application changes. In this post, we'll explore how we identified the bottleneck, redesigned the execution path, and achieved these performance improvements.
The hidden cost of repeated query planning
Looking up a document by its _id is typically a fast operation in MongoDB, thanks to its efficient _id index. However, the original $_internalSearchIdLookup implementation constructed and executed a new aggregation sub-pipeline for every document returned by mongot, even though only the _id value changed:
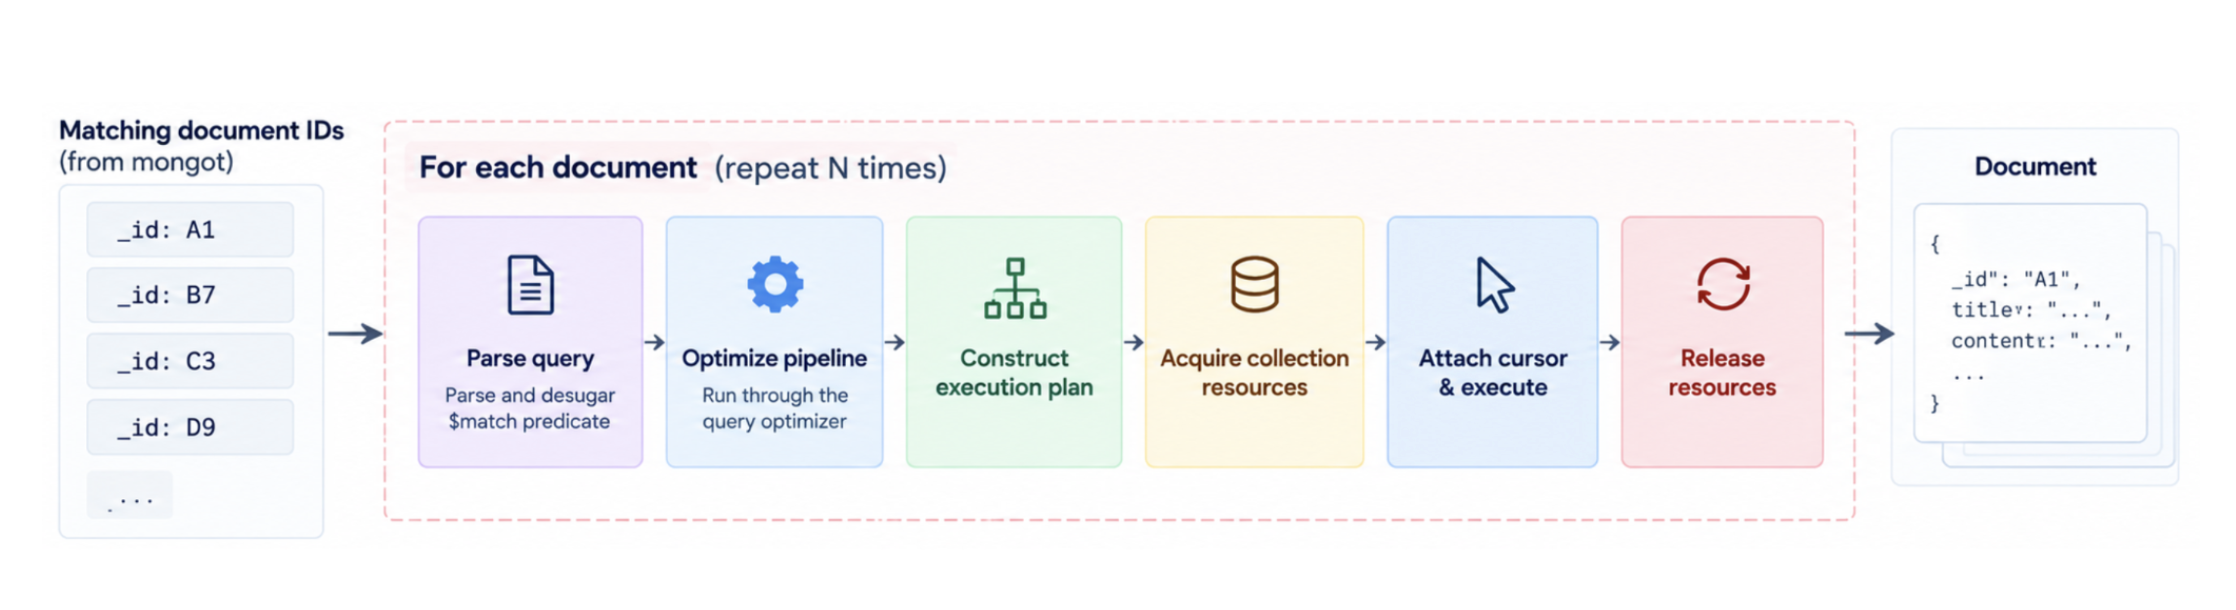
For each document, MongoDB parsed the query, optimized the pipeline, constructed an execution plan, acquired collection resources, attached a cursor, executed the lookup, and released resources.
The problem was not the indexed document retrieval, but the repeated preparation work surrounding it. Even though the query structure was identical across lookups, MongoDB rebuilt the execution plan and reacquired collection resources for every document instead of reusing them. This overhead accumulated linearly with the number of results. For example, a search query returning 1,000 documents could trigger 1,000 separate cycles of query planning, collection acquisition, and resource cleanup. As result sets grew, the repeated preparation work became a substantial contributor to end-to-end search latency. Figure 2 illustrates this repeated execution overhead.
Figure 2. Repeated query planning and resource acquisition for each document lookup.
To quantify this overhead, we profiled representative Vector Search workloads. The results revealed that approximately 30% of mongod CPU time was spent on query plan construction and collection acquisition, rather than retrieving documents. This confirmed that the bottleneck was not primarily the underlying document reads, but the redundant work surrounding them.
Redesigning the document lookup execution path
To eliminate redundant lookup overhead, we redesigned $_internalSearchIdLookup around two key optimizations: reusing parameterized execution plans and batching document lookups to minimize resource acquisition overhead. Together, these changes allow MongoDB to retrieve thousands of documents without repeatedly rebuilding query plans or acquiring collection resources.
1. Reusing a parameterized SBE execution plan
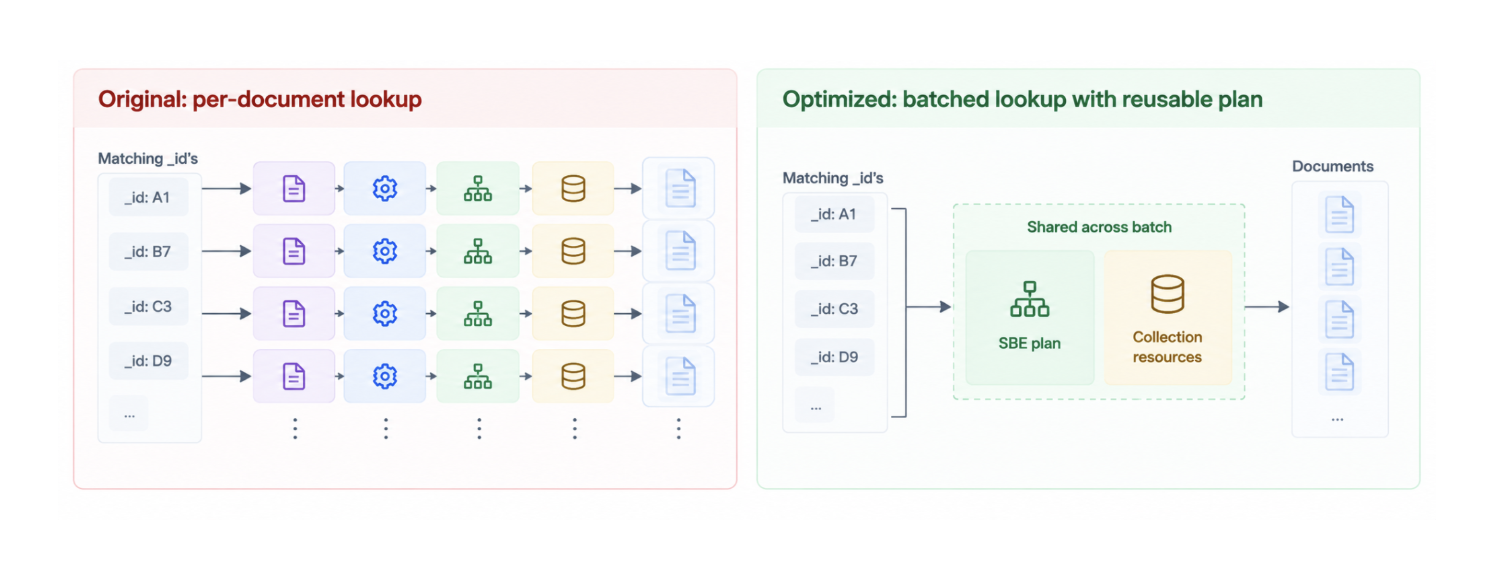
The first major optimization was introducing SbeSingleDocumentLookupExecutor, built on MongoDB's Slot-Based Execution (SBE) engine. The key observation was simple: every document lookup follows the same query structure, and only the _id value changes. Instead of constructing a new execution plan for each document, the optimized executor builds the lookup plan once, caches it, and reuses it by rebinding the _id parameter for subsequent lookups.
For example, when retrieving 1,000 documents, the original implementation could construct 1,000 separate query plans. With the optimized executor, all 1,000 lookups can reuse a single parameterized plan.
This eliminates redundant query parsing, optimization, and plan construction, significantly reducing per-document execution overhead.
2. Batching document lookups to reuse collection resources
While plan reuse eliminates repeated query planning, acquiring and releasing collection resources for every document can still introduce substantial overhead. To address this, we introduced a reusable BatchedEnrichmentStage that buffers incoming search results and processes them within a shared resource scope. Instead of independently acquiring and releasing collection resources for every document, the optimized execution path reuses collection resources across multiple lookups within a batch, amortizing the acquisition and cleanup costs. For example, with 1,000 documents and a batch size of 100, collection resources can be acquired just 10 times instead of 1,000 times, i.e., once per batch rather than once per document. Although the number of document lookups still grows linearly with the result set size, batching significantly reduces the repeated resource management overhead.
Combined with SBE plan caching, this allows thousands of document lookups to share both an execution plan and collection resources, substantially reducing CPU overhead. The result is a more efficient document lookup architecture: build the execution plan once, reuse it across documents, and minimize repeated resource acquisition.
Figure 3 illustrates how the optimized approach eliminates redundant work by reusing execution plans and collection resources across document lookups.
Figure 3. Original per-document lookup vs. optimized batched lookup with shared execution plans.
Performance results: End-to-end latency and throughput
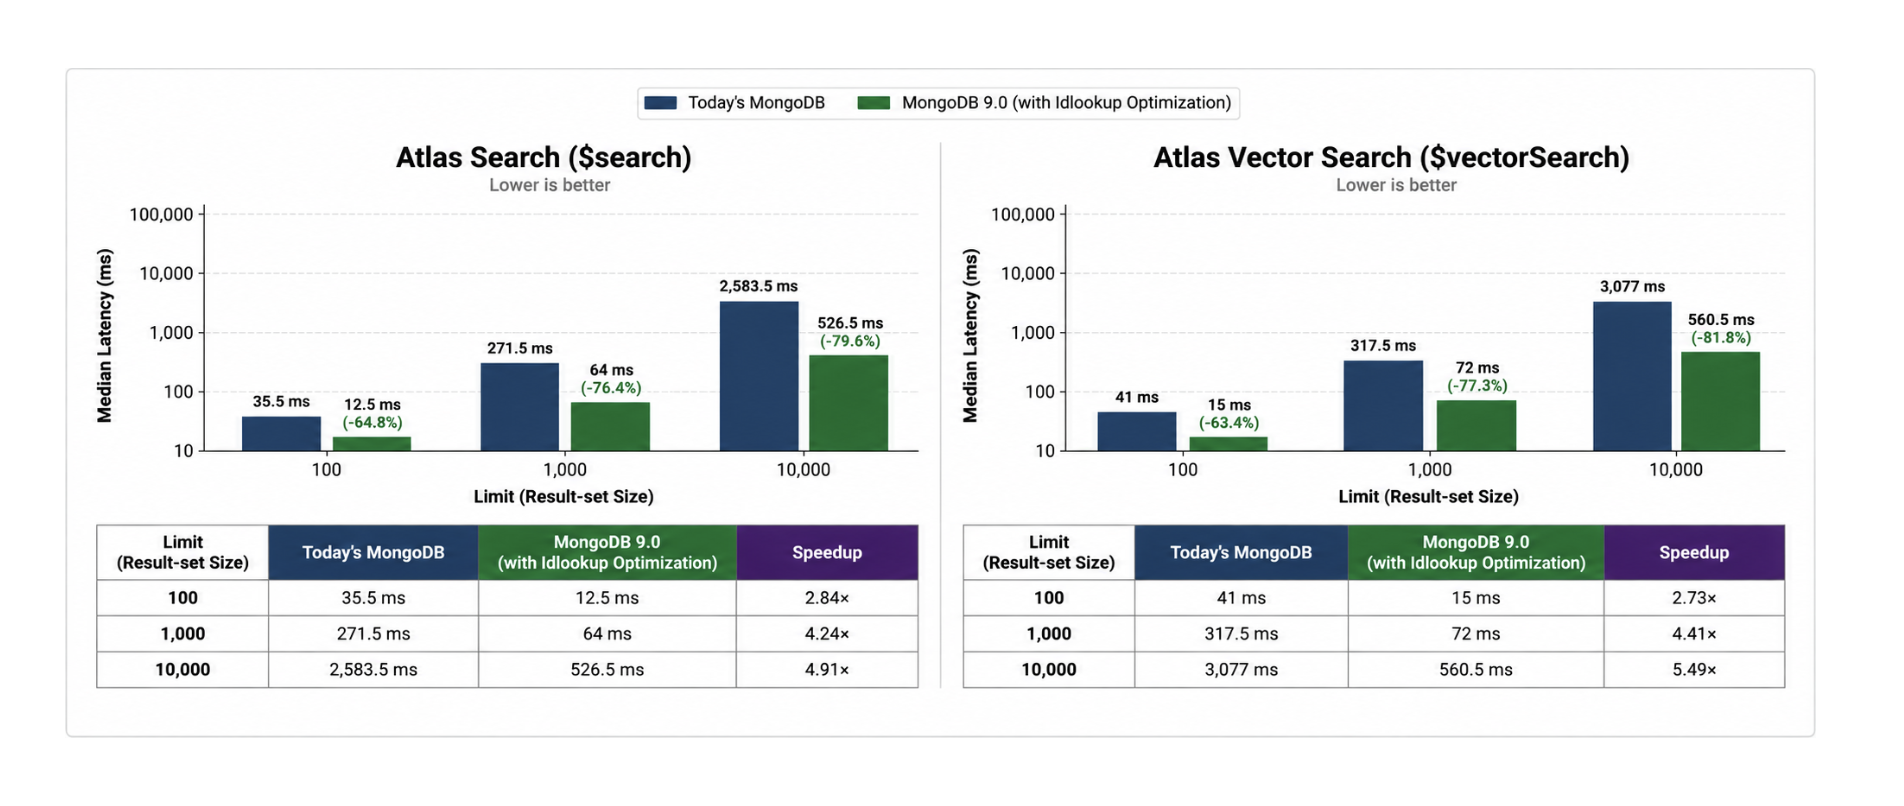
As shown in Figure 4, both Atlas Search ($search) and Atlas Vector Search ($vectorSearch) achieved substantial reductions in end-to-end query latency across all evaluated result-set sizes (100, 1,000, and 10,000 documents). At 10,000 results, median latency dropped from approximately 2.6 seconds to 527 milliseconds for Atlas Search (4.9× faster) and from 3.1 seconds to 561 milliseconds for Atlas Vector Search (5.5× faster).
An important pattern emerges: the larger the result set, the greater the speedup. This is consistent with the underlying optimization. While search execution still incurs its own costs, eliminating repeated query planning and resource acquisition overhead becomes increasingly valuable as more documents are materialized.
Figure 4. End-to-end query latency improvements for Atlas Search and Atlas Vector Search in MongoDB 9.0.
Higher throughput under concurrency
Lower latency is only part of the story. We also evaluated performance under concurrent query execution. With 16 concurrent clients running a $search workload, the optimized implementation delivered:
Approximately 2.75x higher throughput
Approximately 3x lower median latency
These results demonstrate that the optimization does more than accelerate individual queries. By eliminating repeated query planning and resource acquisition, it reduces unnecessary CPU work per document lookup, allowing mongod to process more concurrent search requests with the same execution resources. The approximately 30% CPU overhead identified in our earlier profiling and the nearly 80% latency reduction observed in our benchmarks represent different measurements and workloads, rather than directly proportional improvements.
Real-world customer impact
To understand the potential impact on real-world workloads, we analyzed 163.8 million Atlas Vector Search executions across 610 customer clusters over 90 days. The analysis shows that larger result-set limits are used across a meaningful portion of the customer fleet. At least 40% of clusters execute queries with limits between 21 and 50, and at least 17% execute queries with limits above 100.
These workloads are particularly well-positioned to benefit from the document lookup optimizations, as eliminating repeated query planning and resource acquisition becomes increasingly valuable when more documents are retrieved.
Importantly, these improvements require no application changes. The optimized document lookup path is enabled by default in MongoDB 9.0.7. Applications do not need to rewrite queries, rebuild search indexes, or adopt new syntax. Existing $search and $vectorSearch pipelines can automatically benefit when running on supported configurations.
Faster search, without the extra work
This optimization began with a surprising observation: a simple _id lookup was spending a significant portion of its CPU budget preparing to execute rather than retrieving data. By replacing repeated aggregation planning with lightweight execution, introducing reusable batching infrastructure, and caching parameterized SBE plans, we removed a major source of overhead from Atlas Search and Vector Search. The result is up to 5.5× faster end-to-end queries in our benchmarks, along with substantial throughput improvements under concurrency.
More broadly, this work illustrates an important database engineering principle: sometimes the biggest performance gains come not from making the core operation faster, but from eliminating the unnecessary work surrounding it. This effort was made possible through collaboration across MongoDB’s Atlas Search Query, Query Execution, Query Integration, Database Integration and Observability, and Server Triage & Release teams. Special thanks to Denis Grebennicov from the Database Integration and Observability team for his significant contributions to this optimization effort.
Next Steps
Ready to make your search queries faster? Upgrade to MongoDB 9.0 to take advantage of the optimized document lookup path. Existing $search and $vectorsearch pipelines can benefit automatically in supported configurations, without query rewrites or index rebuilds.