AI MODELS
Voyage AI by MongoDB
Build trustworthy, production-grade AI applications and agents with best-in-class embedding models—accessible via standalone API or natively in Atlas.
High-accuracy retrieval for production AI agents
Maximize your retrieval performance with state-of-the-art accuracy that reduces hallucinations across complex and multimodal data.
- State-of-the-art retrieval accuracy
- Database agnostic
- High performance, low latency

High accuracy embeddings and rerankers
Ground your AI applications and agents with high-accuracy retrieval, powered by state-of-the-art models and advanced capabilities like contextualized chunk embeddings and instruction following.
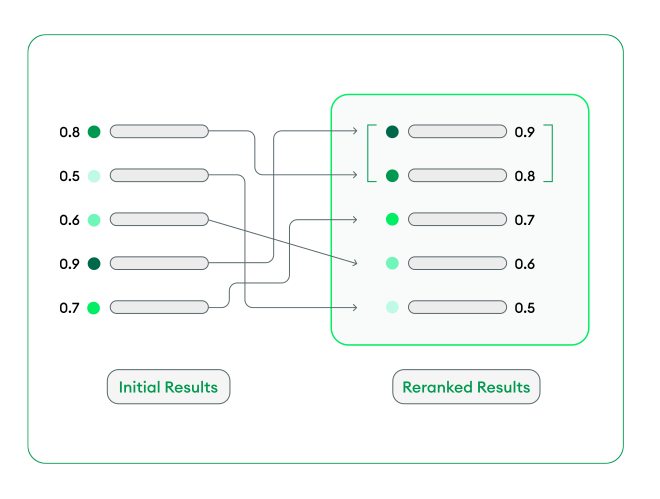
Precision reranking for optimized retrieval
Refine your results to maximize retrieval quality. Leverage the power of cross-encoders capable of instruction following.
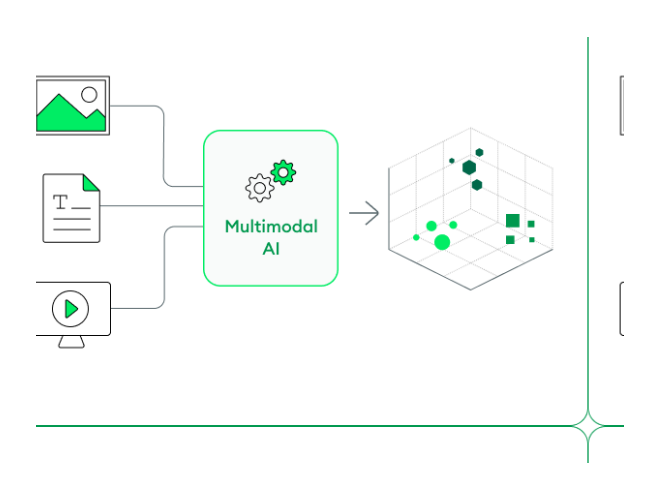
Close the modality gap across all your data
Project text, screenshots, PDFs, and video into a single unified vector space. Designed for systems architects and engineering teams building workflows that must look beyond raw text to parse complex, multimodal documents natively without loss of semantic context.
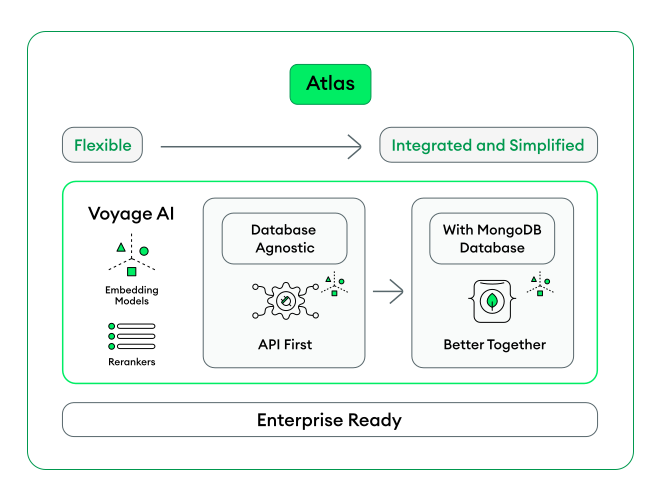
Start flexible. Simplify with confidence.
Start with the flexibility of a database-agnostic API that fits your stack today. As your workflows mature and your needs grow, seamlessly adopt integrated capabilities that simplify operations and reduce coordination across services—secure and governed from day one.
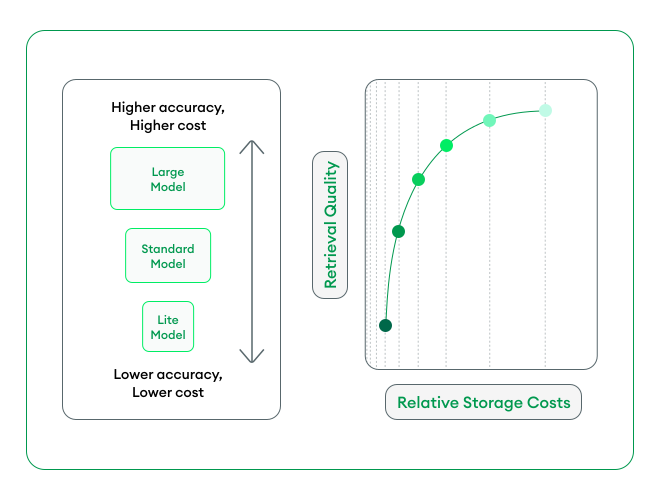
Optimize price performance
Cutting-edge research delivers models at the price-performance frontier. Right-size inference and storage costs without compromising retrieval quality through flexible output dimensions, quantization, and a range of model sizes tailored to your requirements.
Deployment flexibility
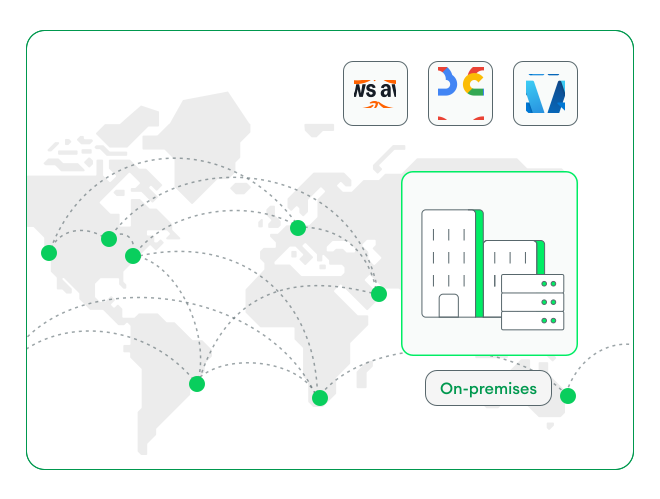
Overcome infrastructure constraints with flexible deployment controls designed for multi-geo and privacy-first operations. Run workloads seamlessly on standard managed cloud APIs, private VPCs, or air-gapped on-premises infrastructure to meet strict compliance mandates.
Pricing for Voyage AI
Architectural flexibility. Operational simplicity.
Cofounder and CEO, TinyFish
Cofounder and CEO, TinyFish
Co-founder and CTO, Factory

Group Head of Technology, TUI Musement

Global VP of Architecture and Governance, Condé Nast
Founder, Tenali AI
Gartner names MongoDB a Leader again
FAQ
No. Voyage AI is built for agnostic utility. While we offer native, high-performance integration for MongoDB Atlas users, our models are available via a standalone API. You can integrate Voyage AI’s high-precision embeddings and rerankers with any database or existing AI framework without vendor lock-in.
Voyage AI utilizes a dedicated third embedding queue engineered explicitly for large-scale auto-embedding. This ensures that large initial sync jobs (up to billions of documents) finish rapidly without affecting the latency or availability of your live application requests.
Power your AI with best-in-class retrieval accuracy
- State-of-the-art retrieval accuracy
- Total cloud neutrality and portability
- Available natively in MongoDB Atlas
- Enterprise-grade security and compliance roadmap
- Free tokens for new users